Netpreme Blog
News, research, and updates from the Netpreme team.
Featured article
Sparse attention
XM-Sparse: Pushing the Throughput Frontier of Sparse Attention with Netpreme X-Mem™
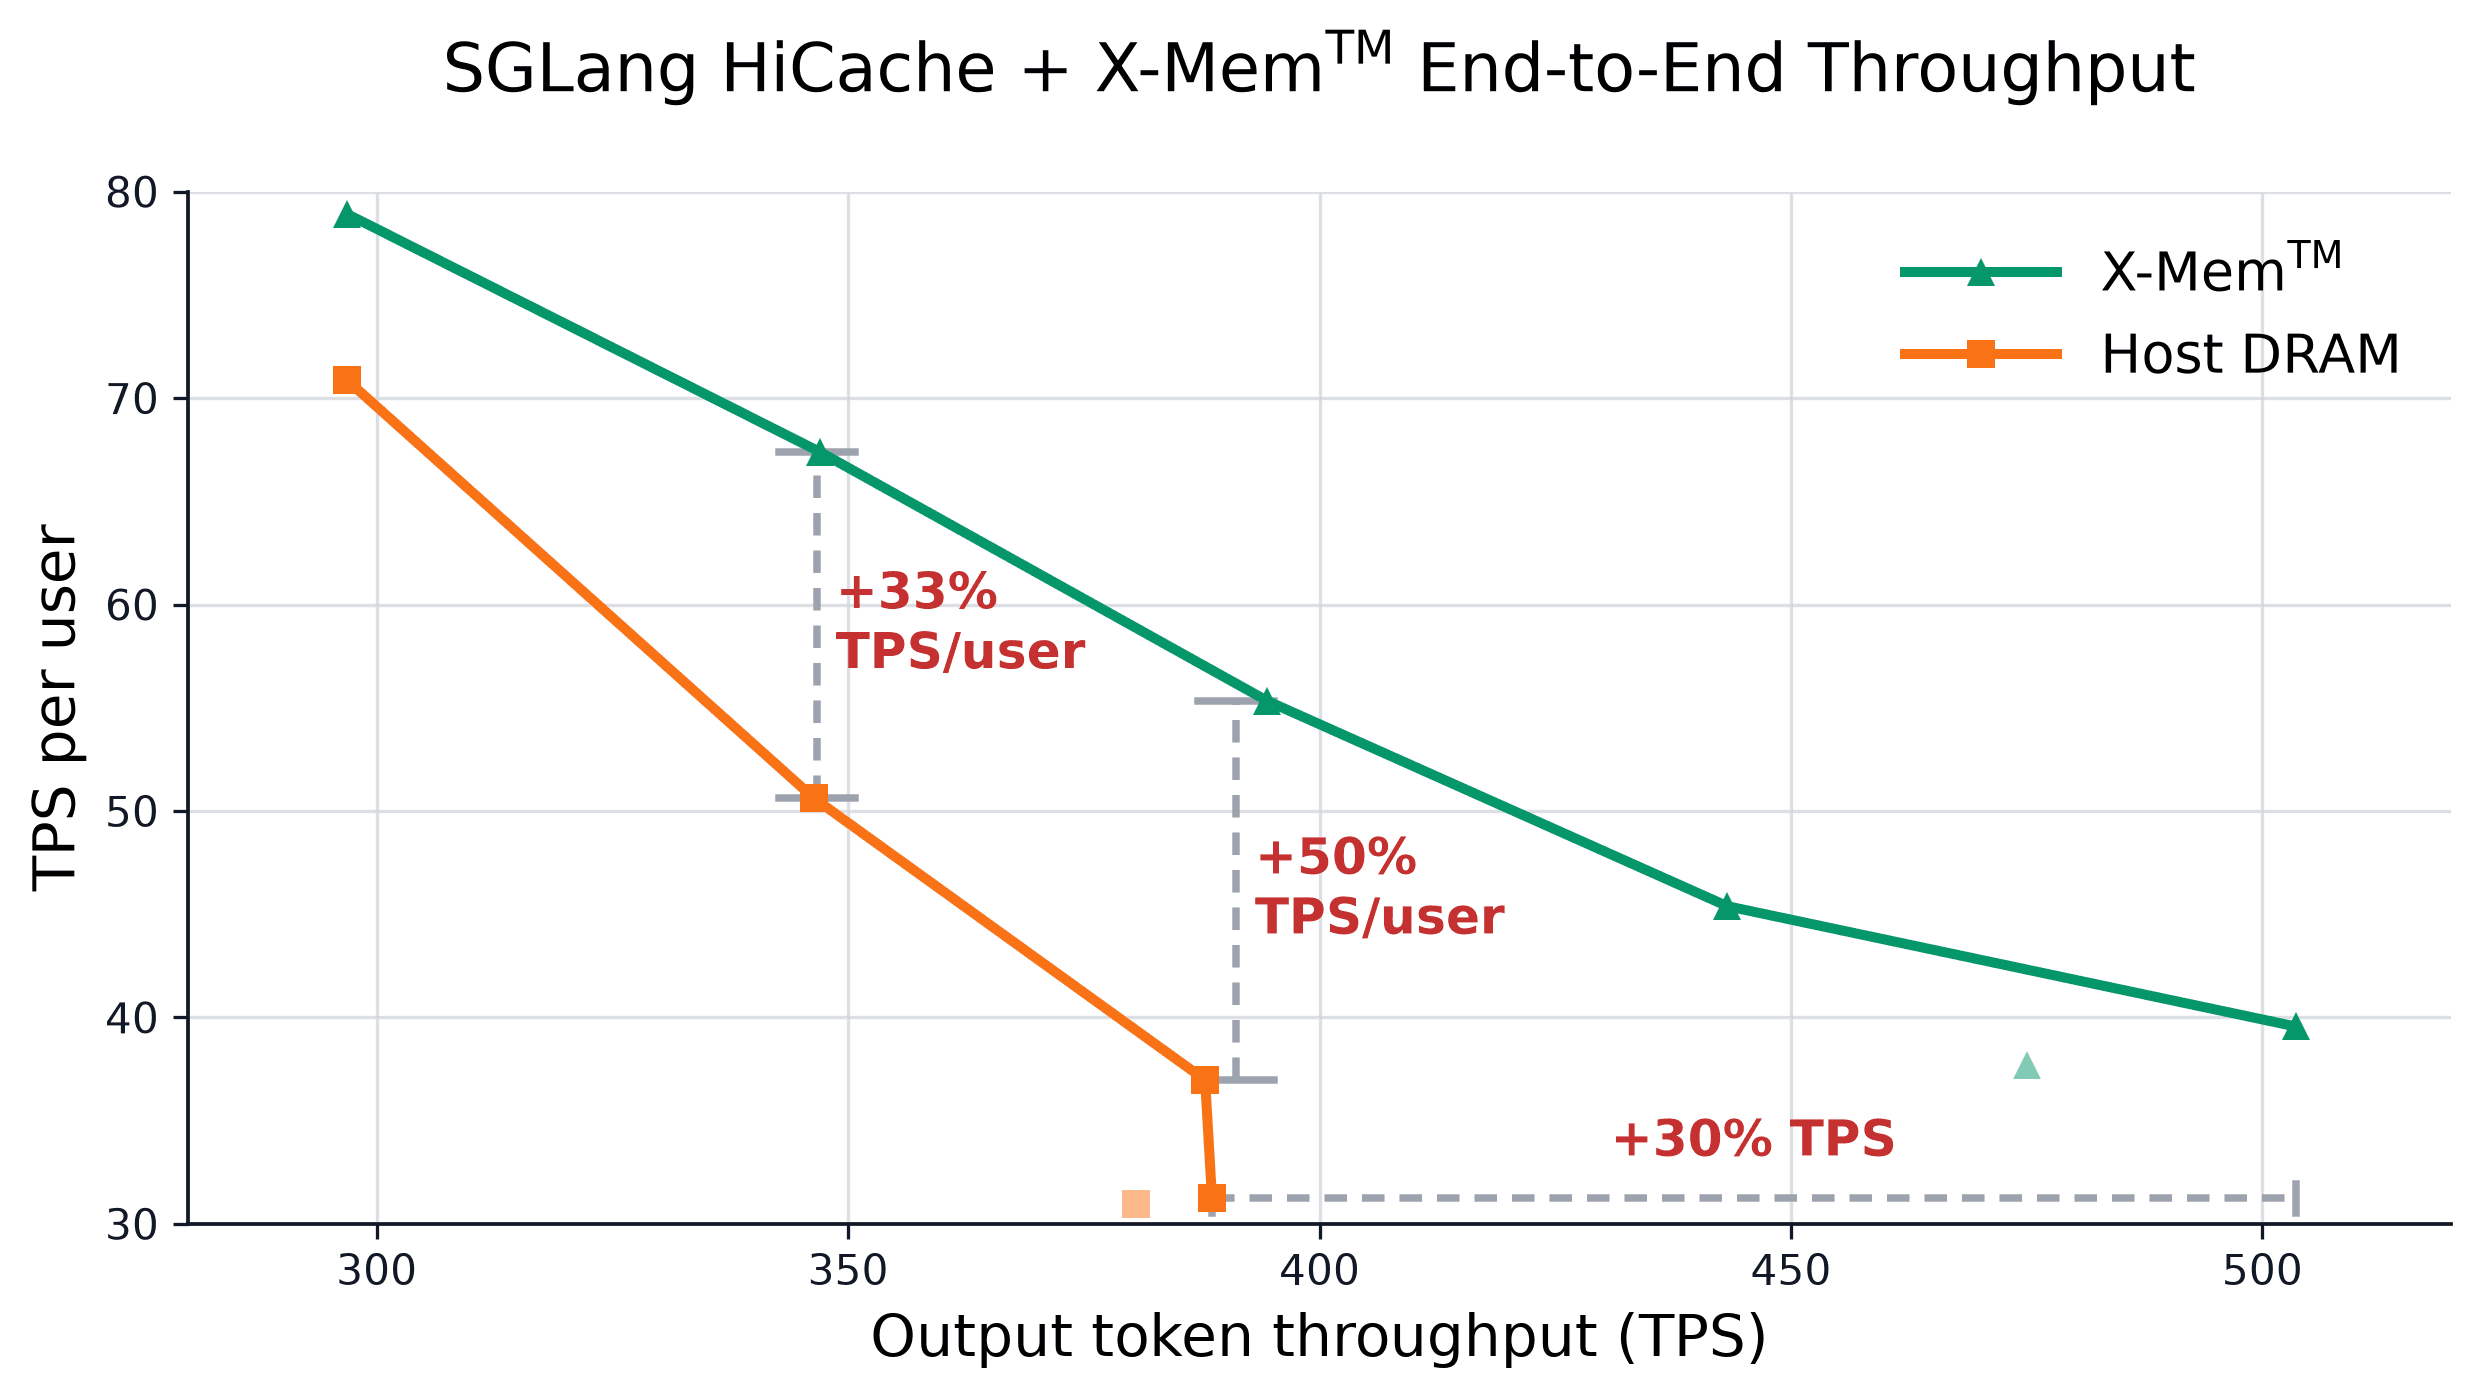
XM-Sparse integrates Netpreme X-Mem™ with SGLang HiSparse. High-bandwidth access to offloaded KV caches reduces decode latency, while the added capacity supports larger batches and higher concurrency.
Read article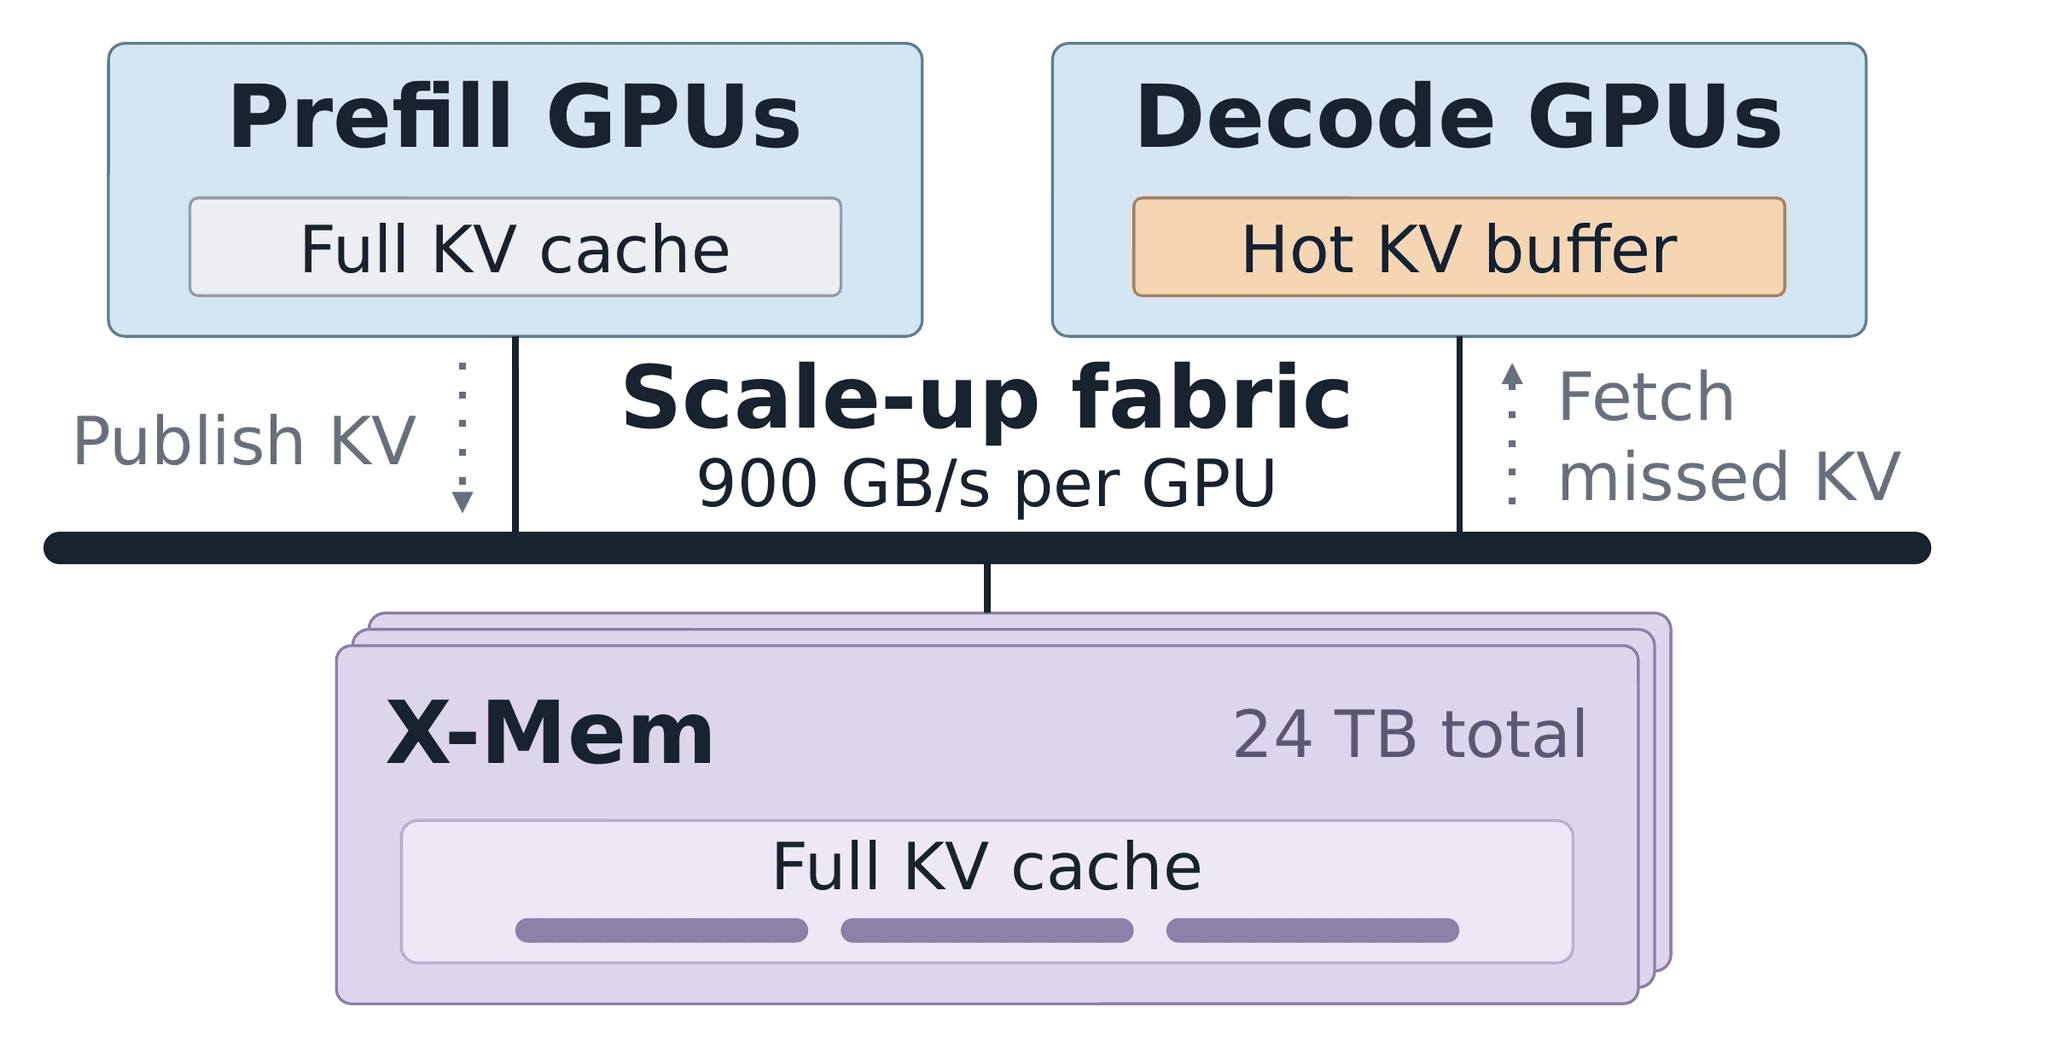
More from Netpreme
- Memory architecture
The Scale-Up Memory Tier
Long-context inference puts pressure on GPU HBM memory. As context grows, KV caches take up more space, competing with model weights and other data for HBM capacity.
Read article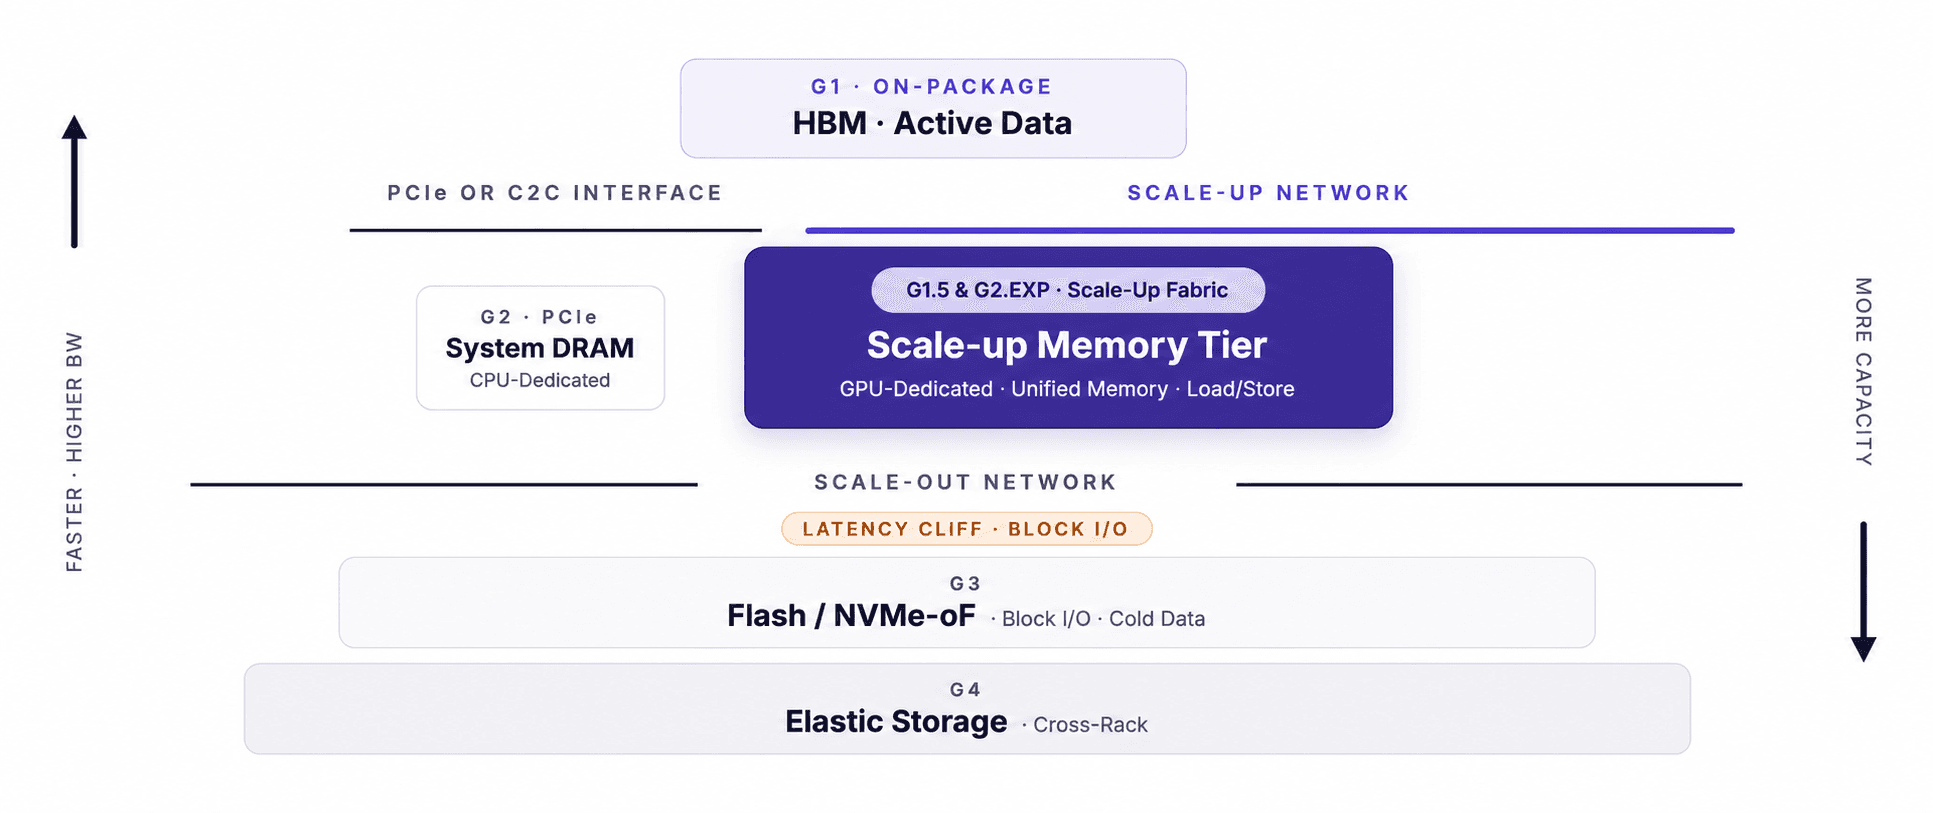
- Events & Insights
Cracking the Memory Wall: Agents, State and the Missing Tier
On October 14, 2026, Netpreme hosted the panel “Cracking the Memory Wall for Next-Gen AI Infrastructure” near the OCP Global Summit with a group of industry leaders:
Read article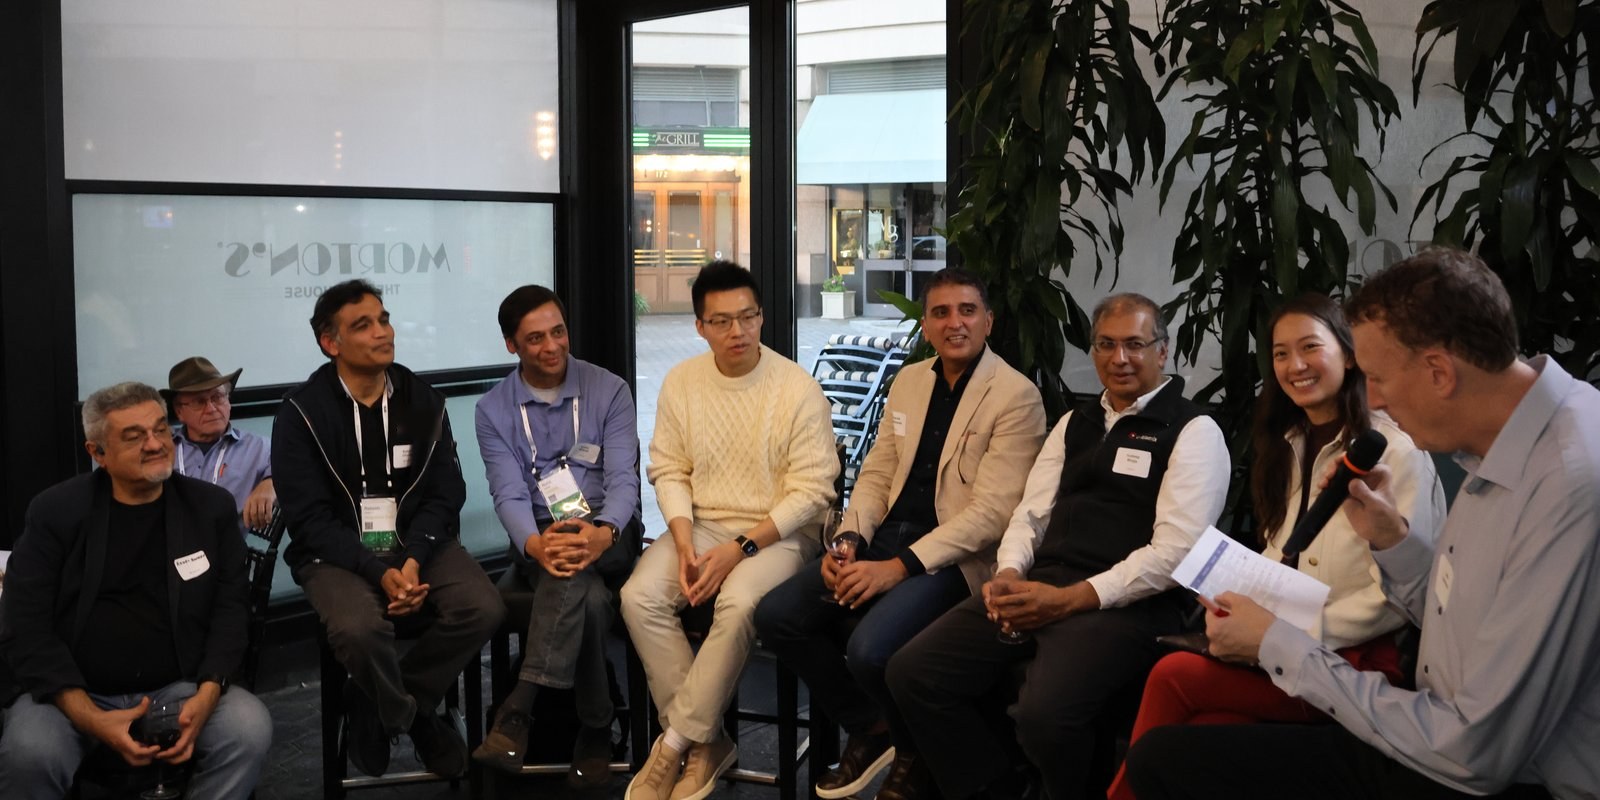
- KV cache
Accelerating SGLang HiCache with Netpreme X-Mem™ MPU
How Netpreme X-Mem integrates with SGLang HiCache as a dedicated TB/s KV memory tier for faster prefix-cache reuse.
Read article